This is the container age. The growing use of services like Docker is transforming the way that software is being handled within enterprises. However, this rise in container utilization does throw present problems for enterprise CIOs when it comes to rolling out applications in production.
One of the biggest issues is scaling applications to meet business demands. While, in theory, containers are able to handle enterprise applications, in practice, they are often hampered by day-to-day disruptions: network failures, server breakdowns or even scheduled maintenance, consequently, organizations have tended to play safe and use containers for stateless web applications, rather than try to overcome these storage issues, indeed some analysts have warned companies to be wary of using stateful application.
Choosing a development tool based on its popularity isn’t a bad idea. Popular tools are usually more stable, and they often have more resources and community support than less popular tools. Developer satisfaction is another key indicator of a good tool, and for the JavaScript ecosystem, I’m going to show you some significant research on both of these criteria.
The list that follows contains all of the main tooling categories for a modern JavaScript developer. It includes the most popular tools for each category according to developer popularity and user satisfaction.
“Explore how Singularity liberates non-privileged users and host resources (such as interconnects, resource managers, file systems, accelerators …) allowing users to take full control to set-up and run in their native environments. This talk explores Singularity how it combines software packaging models with minimalistic containers to create very lightweight application bundles …
Software-defined storage, which until recently was the preserve of large storage solution vendors, can be implemented today with open source and free software. As a bonus, you can look forward to additional features that are missing in hardware-based solutions. GlusterFS puts you in a position to create a scalable, virtualized storage pool made up of regular storage systems grouped to form a network RAID and with different methods of defining a volume to describe how the data is distributed across the individual storage systems.
Regardless of which volume type you choose, GlusterFS creates a common storage array from the individual storage resources and provides it to clients in a single namespace…
Every time I see an article claiming that TDD improves code quality, a part of me cries. It’s not that I don’t think it can be true. It’s because it’s not necessarily true, and those articles rarely bother to provide a satisfying explanation. Here’s my try.
TDD and Better Design
There’s a lot of talking about TDD making your codebase more modular and less coupled, and making the designs you produce being better in general. I think this might be true, mainly because of two factors: the act of design and characteristics of testable code.
This article contains an analysis and solution for blocking of international SPAM botnets with on postfix mail servers by using a postfwd plugin which analyses the sasl connects by country.
One of the most important and hardest tasks for every company that provides mail services is staying out of the mail blacklists. If a mail domain appears in one of the mail domain blacklists, other mail servers will stop accepting and relaying its e-mails. This will practically ban the domain from the majority of mail providers and prohibits that the provider’s customers can send e-mails. Tere is only one thing that a mail provider can do afterwards: ask the blacklist providers for removal from the list or change the IP addresses and domain names of its mail servers.
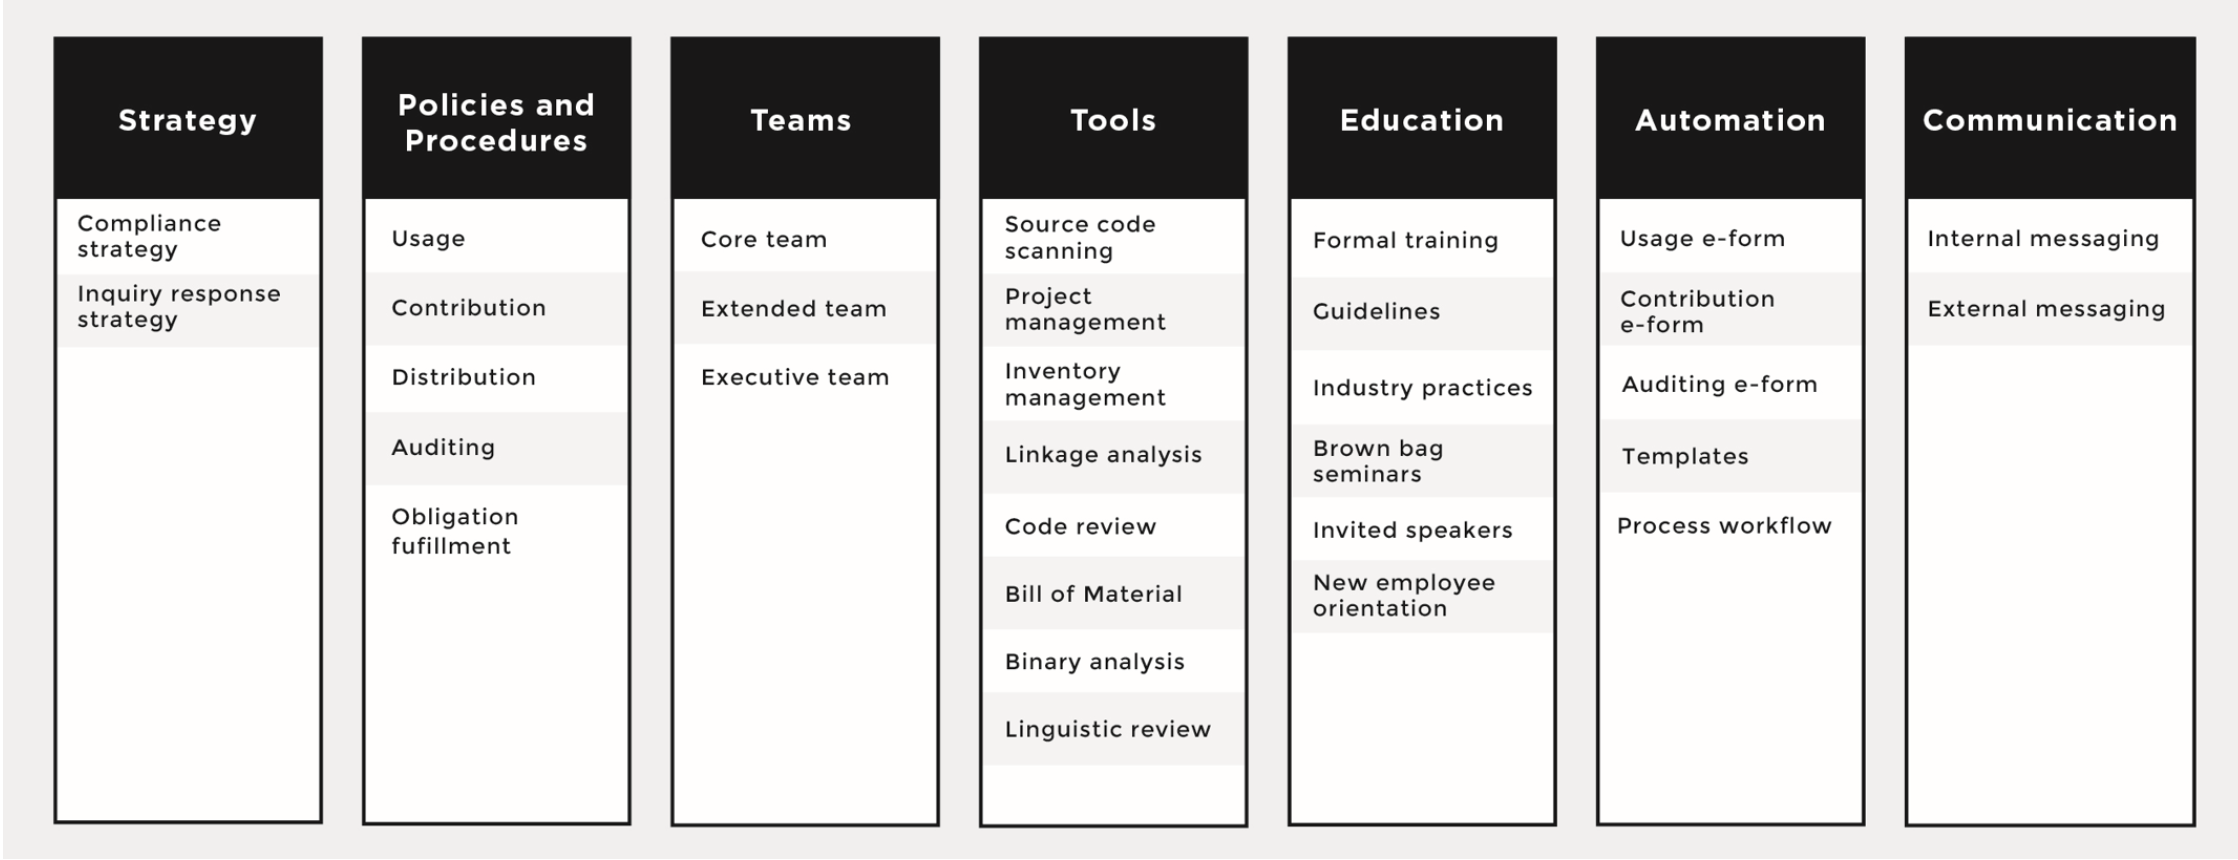
A successful open source management program has seven essential elements that provide a structure around all aspects of open source software. In the previous article, we gave an overview of the strategy and process behind open source management. This time we’ll discuss two more essential elements: staffing on the open source compliance team and the tools they use to automate and audit open source code.
Compliance Teams
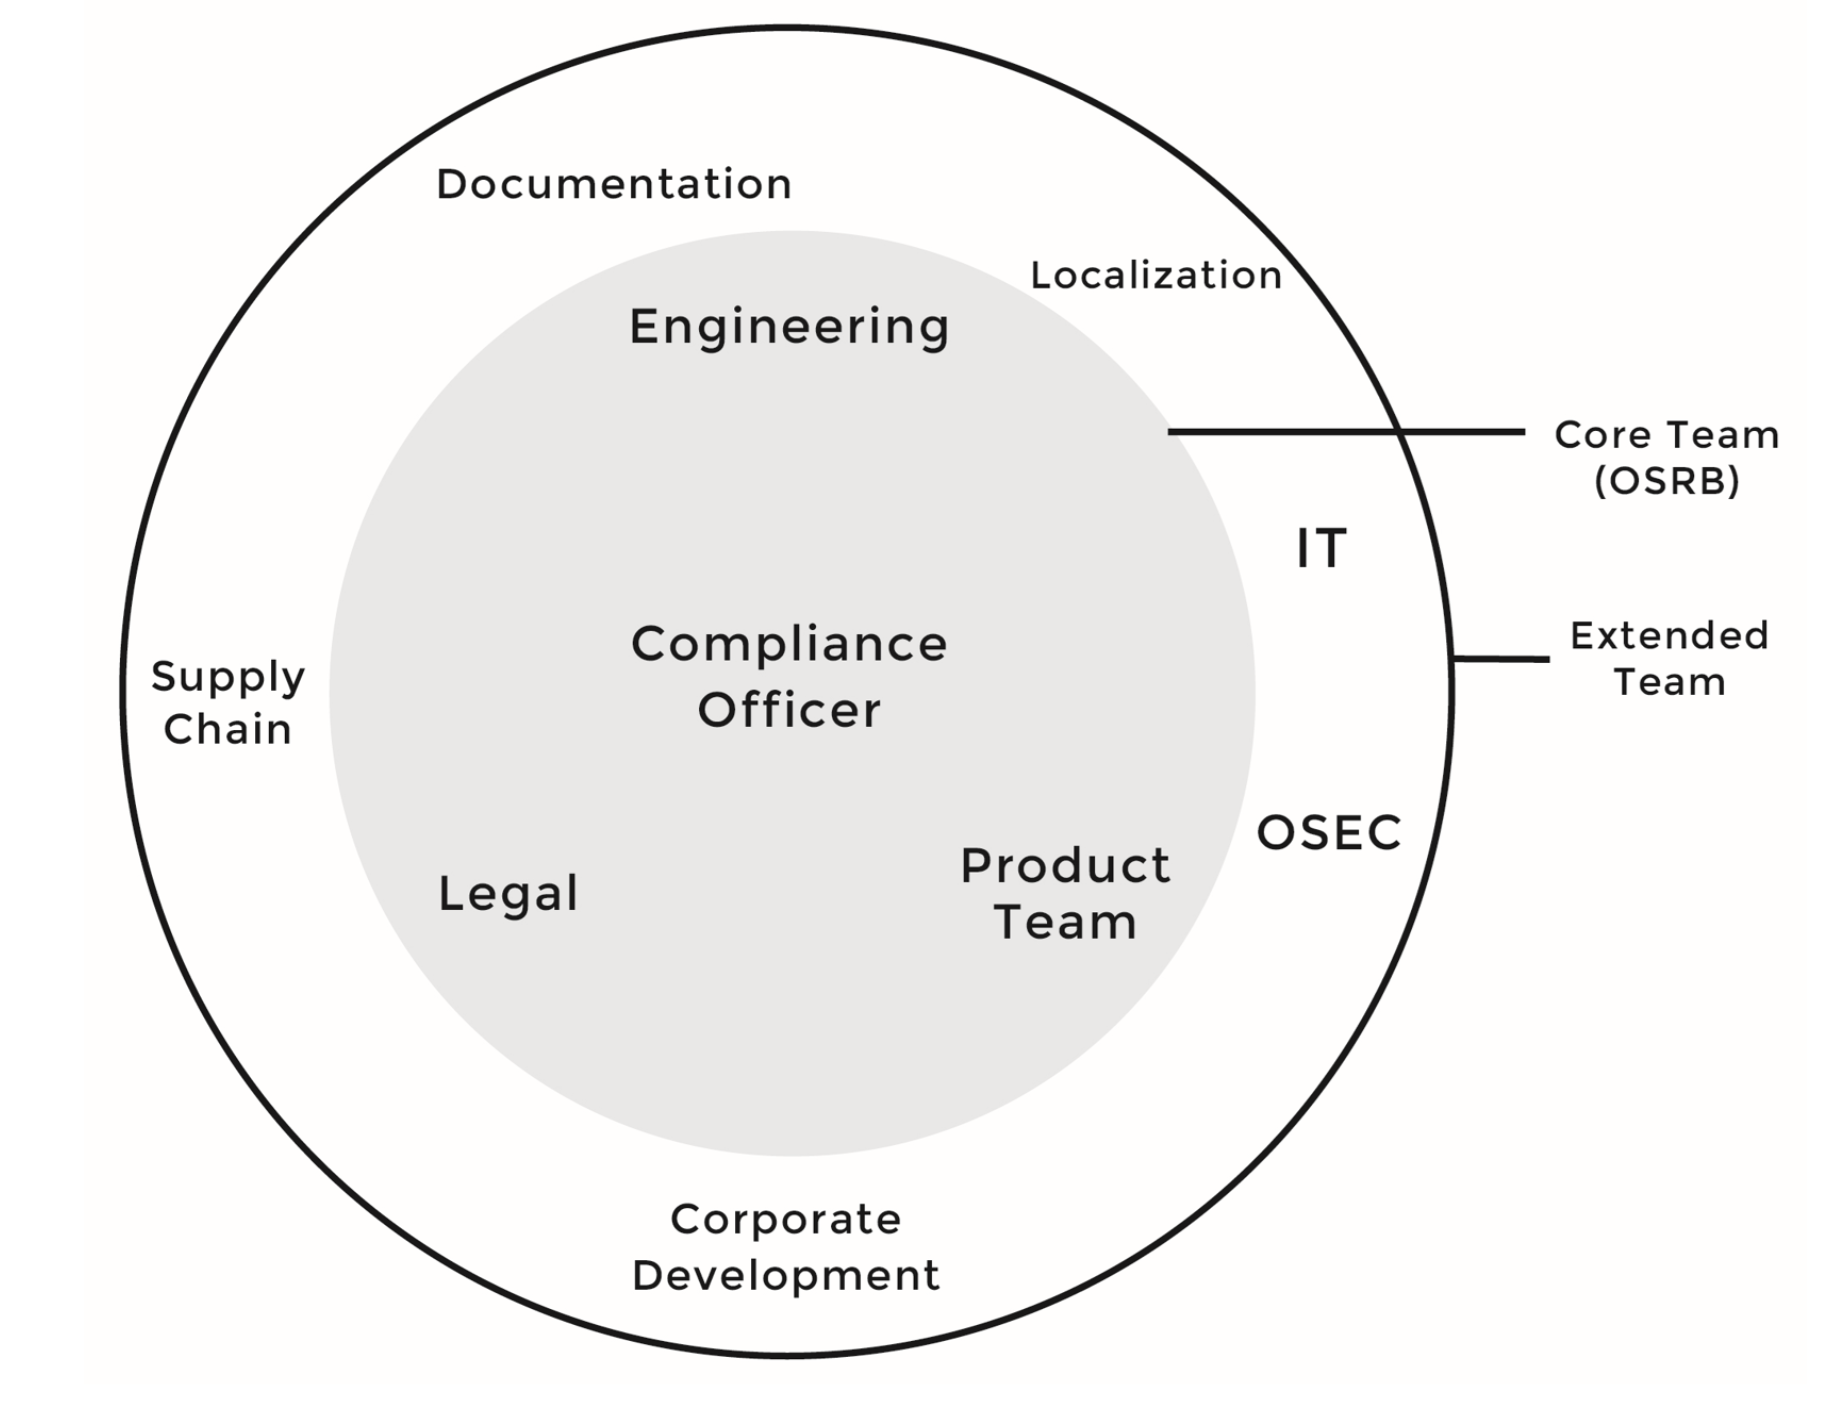
The open source compliance team is a cross-disciplinary group consisting of various individuals tasked with the mission of ensuring open source compliance. There are actually a pair of teams involved in achieving compliance: the core team and the extended team.
The core team, often called the Open Source Review Board (OSRB), consists of representatives from engineering and product teams, one or more legal counsel, and the Compliance Officer.
The extended team consists of various individuals across multiple departments that contribute on an ongoing basis to the compliance efforts: Documentation, Supply Chain, Corporate Development, IT, Localization and the Open Source Executive Committee (OSEC). However, unlike the core team, members of the extended team are only working on compliance on a part-time basis, based on tasks they receive from the OSRB.
Various individuals and teams within an organization help ensure open source compliance.
Tools
Open source compliance teams use several tools to automate and facilitate the auditing of source code and the discovery of open source code and its licenses. Such tools include:
•A compliance project management toolto manage the compliance project and track tasks and resources.
• A software inventory toolto keep track of every single software component, version, and product that uses it, and other related information.
•A source code and license identification tool to help identify the origin and license of the source code included in the build system.
• A linkage analysis tool to identify the interactions of any given C/C++ software component with other software components used in the product. This tool will allow you to discover linkages between source code packages that do not conform to company policy. The goal is to determine if any open source obligations extend to proprietary or third party software components. If a linkage issue is found, a bug ticket is assigned to Engineering with a description of the issue in addition to a proposal on how to solve the issue.
• A source code peer review toolto review the changes introduced to the original source code before disclosure as part of meeting license obligations.
•A bill of material (BOM) difference tool to identify the changes introduced to the BOM of any given product given two different builds. This tool is very helpful in guiding incremental compliance efforts.
Next time we’ll cover another key element of any open source management program: education. Employees must possess a good understanding of policies governing the use of open source software. Open source compliance training — formal or informal — raises awareness of open source policies and strategies and builds a common understanding within the organization.
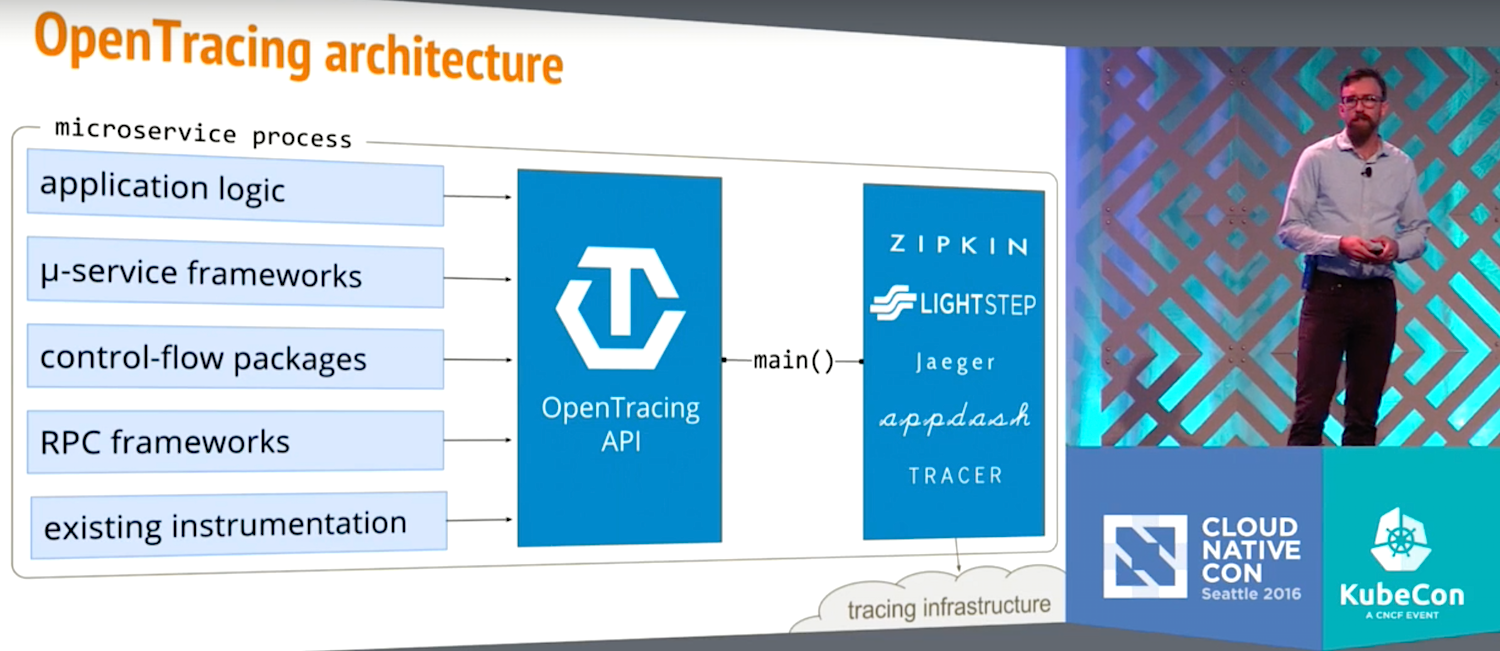
Ben Sigelman shows how OpenTracing can deliver zero-touch, black-box instrumentation of distributed applications via orchestration systems like Kubernetes, and why that could change the way we all reason about distributed computation.
Start exploring Linux Security Fundamentals by downloading the free sample chapter today. DOWNLOAD NOW
Earlier in this series, you learned the types of hackers who might try to compromise your Linux system, where attacks might originate, and the kinds of attacks to expect. The next step is to assess the security risks to your own system and the costs of both securing, and not securing, your assets in order to begin formulating a security plan.
Focusing on likely threats to the highest value assets is a reasonable place to start your risk assessment. A common method for determining likelihood is to create a use case from the point of view of a malicious actor attempting to cause harm to the system.
Next, calculating the value of the assets will help determine the amount of security that should be implemented to protect those assets. It may not always be cost-effective to protect everything. Many types of attacks can be mitigated by implementing minimal security. It is not likely possible to protect all assets, all of the time.
And finally, knowing the potential impact to business operations is also essential in determining the level of security required for any particular asset. If the business is severely impacted due to a compromise, then more resources should be dedicated to maintaining the security of the assets. Another business consideration is the impact of adding additional security to the environment, possibly creating a performance challenge.
Let’s look at each of these areas in turn and some important factors to consider and questions to ask as you’re evaluating the trade-offs.
Likelihood
Evaluating the feasibility of a potential attack is important. Is the threat real or theoretical? You can begin to asses the risk by asking:
• Method: Are the skills, knowledge, tools, etc. available?
• Opportunity: Is there time and access?
• Motive: Is it an intentional act or an accidental damage?
Recently, it has been demonstrated that fingerprint scanners on smart phones can be fooled into thinking an authorized user has scanned their fingerprint. The researchers claimed that the attack was rather easy to accomplish. The reality is that the particular attack required a fair amount of specific things to happen in proper order to be successful. This is rather unlikely.
Even if the methods are well-known, if the tools are difficult to acquire, only the most resource-wealthy will be able to perpetrate the attack. Access and opportunity are also areas that can be designed into a system, such that attacks can only be accomplished during certain windows. By limiting the opportunity to certain situations, time-based or access-based, security costs can be reduced outside of those situations.
Asset Value
A thorough inventory of business assets will be the basis for the valuation required when determining what and how much security will be required.
Most environments handle this process via an Asset Management System. The roles of each asset will also determine the importance of the asset in the business operations. Components that are not expensive and yet carry large responsibility for operations should be considered highly valuable. Estimating the impact of a service outage, damage to the infrastructure, or compromise will also be necessary in determining the value of the assets.
To determine asset value, you should:
• Identify network/system/service assets
• Determine asset roles and relationships
• Evaluate the impact of asset damage/failure/loss.
In part four we’ll consider the difficulty of estimating the cost of a cyber attack and give you some questions to ask when weighing the cost of protecting your business assets, with the business impact of a potential security compromise.
Stay one step ahead of malicious hackers with The Linux Foundation’s Linux Security Fundamentals course. Download a sample chapter today!
Microservices and services-oriented architecture are here to stay, but this kind of distributed system destroys the traditional type of process monitoring. Nonetheless, companies still need to understand just what’s happening inside the flow of an application. Ben Sigelman, Co-founder of LightStep, said at his keynote at CloudNativeCon that by adopting a new standard for distributed applications called OpenTracing can tell those stories without building complex instrumentation, or fundamentally changing the code of your application.
“If you previously told a story about what happened in your process in that way with this squiggly line going through a single process, that story is gone,” Sigelman said. “In our conversations with numerous companies that have adopted this sort of technology, what they’ve been telling us is that, as they decouple their systems and their transactions I/O, behold they are no longer on any single process, they are literally unable to answer the most basic questions about what’s happening.
“The solution historically for this has been distributed tracing,” Sigelman said. “It still is a solution and it’s wonderful. So the question is, why isn’t it ubiquitous? … That is what OpenTracing is here for. The reason is the instrumentation has been too difficult. It’s required you to instrument not just across processes but across library boundaries in a way that often couples you to poorly engineered libraries that were written in an afternoon or a weekend by someone.”
OpenTracing is a vendor-neutral API standard, not something that one deploys, Sigelman said. Instead it’s something you program against, something you build into your microservices architecture. The OpenTracing API sits in the middle of the microservices process, like application logic, control-flow packages or existing instrumentation, and tracing infrastructure like LightStep, Zipkin, or Jaeger.
Sigelman showed how OpenTracing works through a demo involving a fake donuts-as-a-service website he created (DonutSalon.com, imbued with the glorious motto “Move Fast and Bake Things”), showing how to track where bottlenecks occurred when the audience faithfully ordered free donuts all at once.
“This can be really powerful if you think about a real system, in that any time you have a latency issue, it’s probably due to some kind of throughput concurrency bottleneck,” Sigelman said. “Being able to actually root-cause where these requests came from in the distributed system is actually fairly profound and something that is not possible with logging at the local level.”
In a Kubernetes system, OpenTracing tracks both the breadth of transactions (called “spans”) and the depth (the communication between clients and services, called “references”). Just tracking one or the other is essentially traditional logging, Sigelman said, but capturing both leads to a much better picture of the traffic in a distributed applications.
“I think it’s possible to get good quality tracing and avoid the pain and suffering of adding a lot of instrumentation or even really changing an application in meaningful ways if we can add the existing API standardization of OpenTracing to a little bit of magic between applications, client proxies, and then the network that connects containers to each other,” he said.
Watch the complete presentation below:
Want to learn more about Kubernetes? Get unlimited access to the new Kubernetes Fundamentals training course for one year for $199. Sign up now!