It’s a shame that many of you haven’t heard of, never mind use, Fail2Ban. I’ve found it to be a very useful and easy way to protect servers that is just as easy to install and deploy.
Working with cryptographic libraries is hard, and a single implementation mistake can result in serious security problems. To help developers check their code for implementation errors and find weaknesses in cryptographic software libraries, Google has released a test suite as part of Project Wycheproof.
“In cryptography, subtle mistakes can have catastrophic consequences, and mistakes in open source cryptographic software libraries repeat too often and remain undiscovered for too long,” Google security engineers Daniel Bleichenbacher and Thai Duong, wrote in a post announcing the project on the Google Security blog.
The Internet of Things offers the promise of all sorts of nifty gadgets, but each connected device is also a tempting target for hackers. As recent cybersecurity incidents have shown, IoT devices can be harnessed to wreak havoc or compromise the privacy of their owners. So Microchip Technology and Amazon.com have collaborated to create an add-on chip that’s designed to make it easier to combat certain types of attack—and, of course, encourage developers to use Amazon’s cloud-based infrastructure for the Internet of Things.
2016 saw the rise of the blockchain evangelist. Not since the heady dotcom days have we seen so many experts hyping a new technology. But, amid the hype, little attention has been paid to an important question. Who pays for the blockchain?
This consideration is especially important to anyone evaluating blockchain technology for their organization.
The blockchain buzz began in 2015. Bitcoin’s association with illegal activities earned it a bad reputation. This led startups to brand themselves as blockchain companies. They promised to deliver the benefits of the “technology behind bitcoin” without the undesirable baggage. Most didn’t understand that the technology behind bitcoin has existed for years.
Bitcoin’s success is a result of the network’s economic incentives.
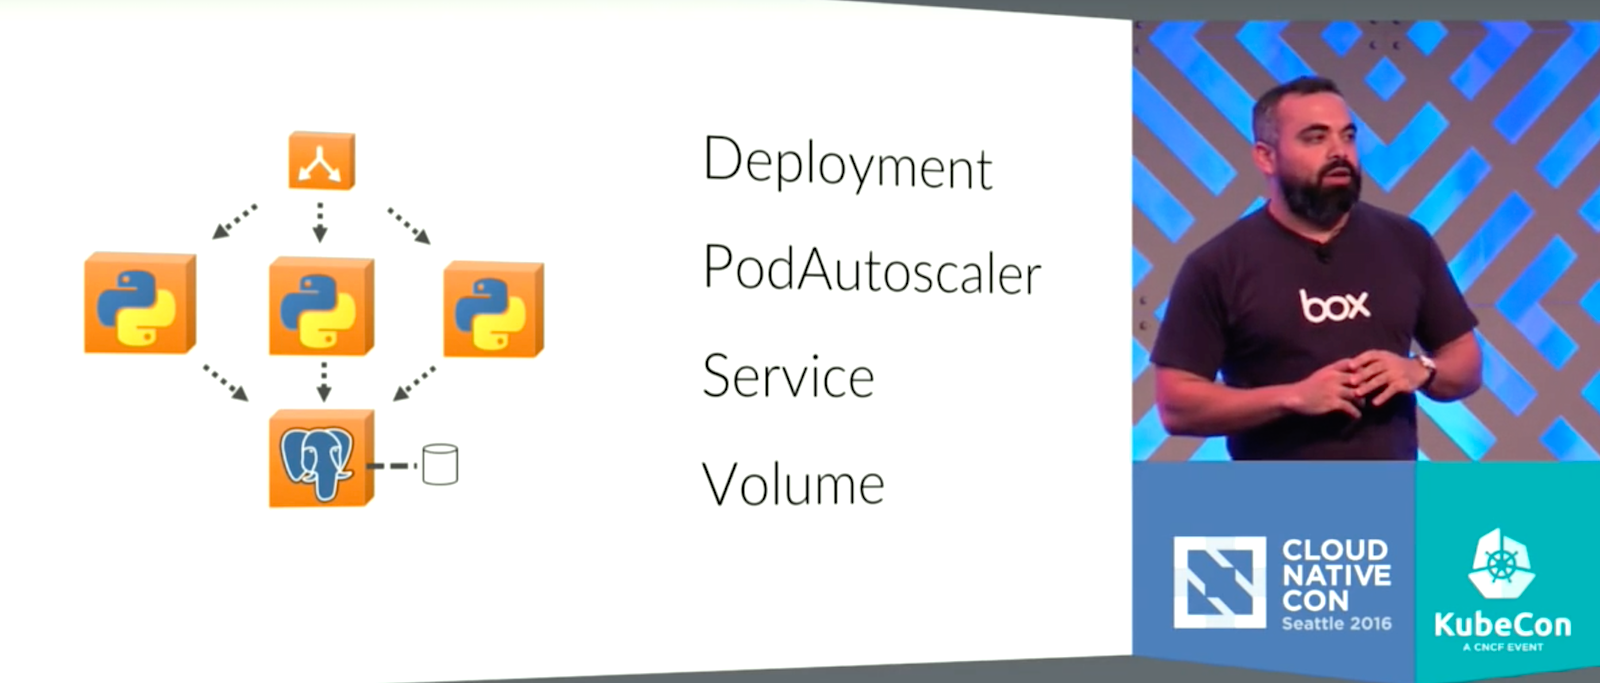
The Kubernetes community is building a platform that will make application development completely cloud infrastructure agnostic. Sam Ghods, co-founder of Box, said Kubernetes’ combination of portability and extensibility put it in a class of its own for cloud application development, during his CloudNativeCon keynote in November.
“We finally have a portable abstraction to work against in cloud infrastructure,” he said.
Ghods compared Kubernetes to other platforms like Linux, which provides consistency across almost any hardware, Java, which runs on almost any operating system, and Twilio, which provides a single platform across dozens of complicated telephony services. The whole idea is to get the messy bits in the background and create a consistent and predictable layer for creation.
“A platform abstracts away a messy problem so you can build on top of it,” Ghods said.
Currently, each of the major cloud infrastructure providers — like Amazon Web Services, Google, Microsoft Azure, and OpenStack — offers different solutions for autoscaling, load balancing, and remote storage, and no solution at all for service discovery.
As a platform, Kubernetes rises above the mess and provides a single layer where developers can be certain that the specifications needed to run the application they’re creating will always exist. That way, no attention is required to deal with how each infrastructure will fulfill the application’s requirements.
“Now, I can write one JSON spec and submit that to any Kubernetes cluster running anywhere and be able to recreate exactly the right topology and exactly the right infrastructure that I need,” Ghods said.
That’s the portability piece of the platform, Ghods said. For extensibility — which Ghods said was the piece he was the most personally excited about — the community is constantly releasing new features and projects to set Kubernetes apart. One such feature is Dashboard, a UI to show resource utilization. Another key component under development is cluster federation for load balancing, and the etcd operator recently introduced by CoreOS, ensures the application is running in the desired state on the cluster.
Ghods said he’s been implementing Kubernetes at Box for the last two years, and the inclusivity and transparency of the community are what set the project apart from other attempts at creating a stable cloud application platform.
“Kubernetes has the opportunity to be the new cloud platform,” Ghods said. “I think the tooling we’re seeing is just the tip of the iceberg. I think the amount of innovation and leverage that’s going to come from being able to standardize on Kubernetes as a platform is incredibly exciting, more exciting than anything I’ve seen in the last 10 years of working on the cloud.
“We have an opportunity here in this room to do what AWS did for infrastructure, but this time in an open, universal, community-driven way,” Ghods sadi. “We can build tooling that people today only dreamt of having and truly uplevel the next generation of developers.”
Do you need training to prepare for the upcoming Kubernetes certification? Pre-enroll today to save 50% on Kubernetes Fundamentals (LFS258), a self-paced, online training course from The Linux Foundation. Learn More >>
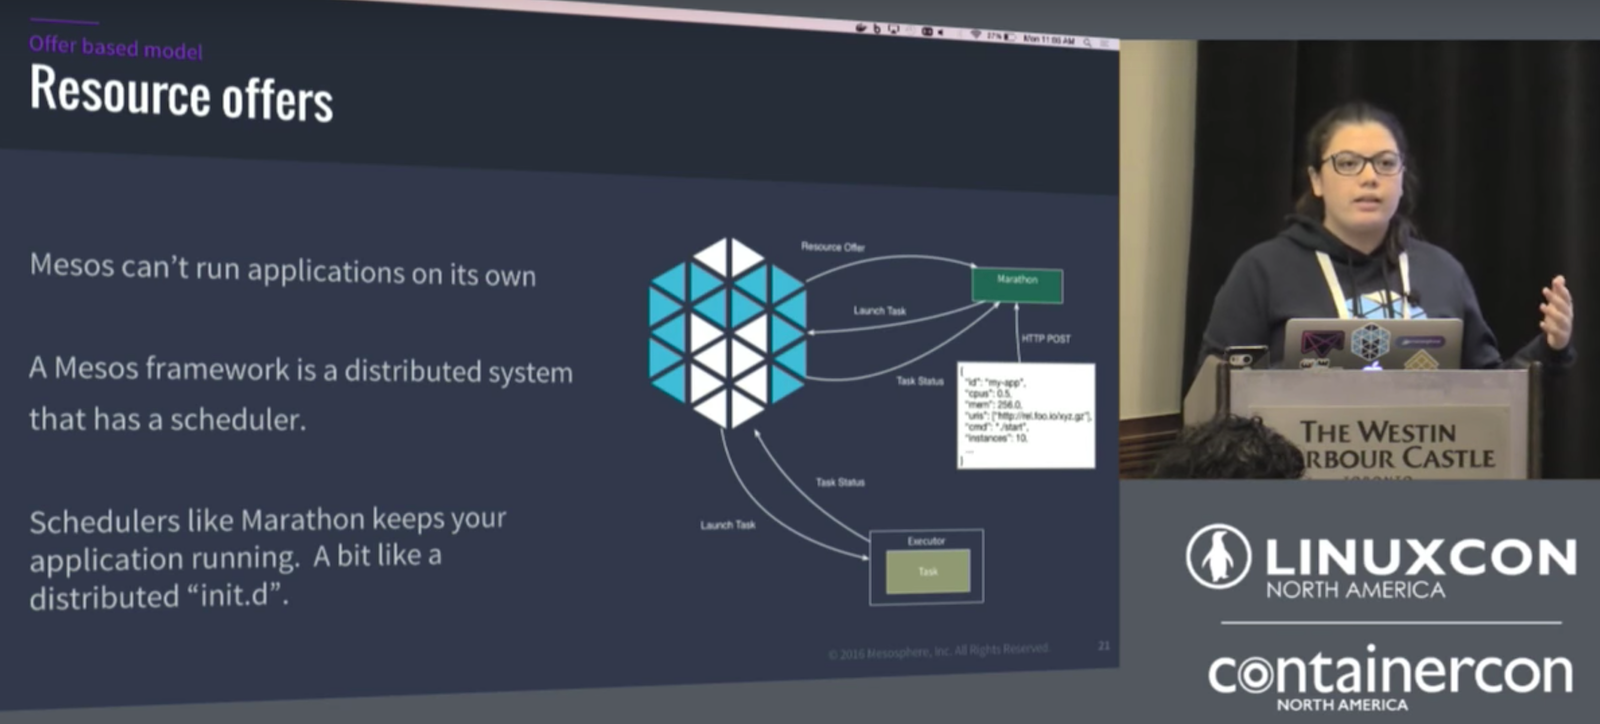
Running applications in our brave new container orchestration world is like managing herds of fireflies; they blink in and out. There is no such thing as uptimes anymore. Applications run, and when they fail, replacements launch from vanilla images. Easy come, easy go. But if your application needs to preserve state, it and must either take periodic snapshots or have some other method of recovering state. Snapshots are far from ideal as you will likely lose data, as with any non-graceful shutdown. This is not optimal, so Apache Mesophere’s Isabel Jimenez and Kapil Arya presented some new ideas at LinuxCon North America.
Arya explains how managing stateless applications is different from managing stateful applications: “When you scale up, you basically launch the new instances, or new loads, or a new cluster. They are pretty much starting all from the vanilla image, the idea being that everything is immutable. When you want to scale down, you just kill the extra instances. If the need comes and you want to, say, schedule some high-priority task, you can easily kill the additional instances that are no longer needed or that need to be preempted, and your high-priority task can actually get the node or the resources right away.”
Stateful applications are different. “To kill an application that is already running, if it’s not a graceful shutdown, then you lose the computation time, and so on. Basically, what that means is, if you have a high-priority task coming in, then killing some instances of the stateful application will definitely result in some compute time loss.”
Container orchestration tools are more optimized for stateless applications. How can we make it better for stateful applications? Arya says, “Make them stateless.” How? One way is to start from scratch. Rewrite your stateful apps to be stateless. That is probably not going to happen. Instead, you could offload the job of managing state to your container orchestration framework and migrate your processes. “We’ll see what actually is involved in doing such a migration. This is a very general recipe that pretty much works on all these scenarios. You first pause the running process, or the container, or the virtual machine, so that the state is now immutable. You then take a snapshot of the current state. You copy over the snapshot to the target node, or the new data center, or the new cluster. Finally, you restart from that snapshot that you just took, and you have the application or the virtual machine up and running.”
Taking the snapshot is referred to as checkpointing. Ideally this happens very quickly, in milliseconds, so that nobody notices any interruptions or delays. Several factors influence this, especially the memory footprint of the application. Arya says that “If you have a memory footprint of a gigabyte, and you’re writing a checkpoint image to a regular disk, then assuming there’s roughly 100 megabytes per second, it’ll take 10 seconds to dump the checkpoint image. If you have some fancy hardware back end, like Cluster File System, then you can get pretty amazing speeds like 60 gigabytes per second or so.”
Watch the complete presentation (below) to learn more details of how Apache is building this functionality into Mesos and to see it demonstrated.
etcd is a key-value store for the most critical data of distributed systems. Use cases include applications running on Container Linux by CoreOS, which enables automatic Linux kernel updates. CoreOS uses etcd to store semaphore values to make sure only subset of cluster are rebooting at any given time. Kubernetes uses etcd to store cluster states for service discovery and cluster management, and it uses watch API to monitor critical configuration changes. Consistency is the key to ensure that services correctly schedule and operate.
Reliability and robustness is etcd’s highest priority. This post will explain how etcd is tested under various failure conditions.
Current most popular container orchestration tools do not offer a failover mechanism for stateful Applications. In this talk from LinuxCon, Apache Mesophere’s Isabel Jimenez and Kapil Arya demonstrate container migration on an Apache Mesos cluster and a more enjoyable way to schedule your Containers.
The Kubernetes community is building a platform that will make application development completely cloud infrastructure agnostic. Sam Ghods, co-founder of Box, said Kubernetes’ combination of portability and extensibility put it in a class of its own for cloud application development, during his CloudNativeCon keynote in November.
This year (2016) I accepted as much incident response work as I could. I spent about 300 hours responding to security incidents and data breaches this year as a consultant or volunteer.
This included hands on work with an in-progress breach, or coordinating a response with victim engineering teams and incident responders.
These lessons come from my consolidated notes of those incidents. I mostly work with tech companies, though not exclusively, and you’ll see a bias in these lessons as a result.