
Idit Levine, CTO of the Cloud Management Division at Dell EMC, presented the open source project UniK and announced new features to make unikernel creation more attractive and viable, both for cloud computing and Internet of Things devices.
Open source development is accelerating networking technology in areas including software-defined networking, open standards, and orchestration. Projects such as OPNFV, OpenDaylight, and recently open sourced ECOMP with many others hosted by The Linux Foundation, are helping drive open source networking innovation.
To help you learn more and give you a sneak peek of Open Networking Summit in April, Arpit Joshipura, General Manager, Networking & Orchestration at The Linux Foundation, will hold a free webinar next week exploring the following topics:
How has networking evolved and where is it heading?
A sneak peek at the future architecture of enterprises and service providers
Why automation at the network and orchestration layers have simplified adjacent markets and industries
“We are entering phase three of open source software-defined networking which is about production-ready solutions deployed at scale,” said Joshipura. “In this webinar, you’ll learn how various open source components come together to create an end-to-end solution.”
This webinar will discuss open source innovations and technologies that enable end-to-end solutions for enterprises, carriers, and cloud. It will also describe open standards and open architectures in adjacent markets such as containers, cloud native, and IoT.
Join SDxCentral and The Linux Foundation for “Open Source Networking & Orchestration: From POC to Production” on Thursday, February 9, 2017 at 10:00am Pacific. Register now >>
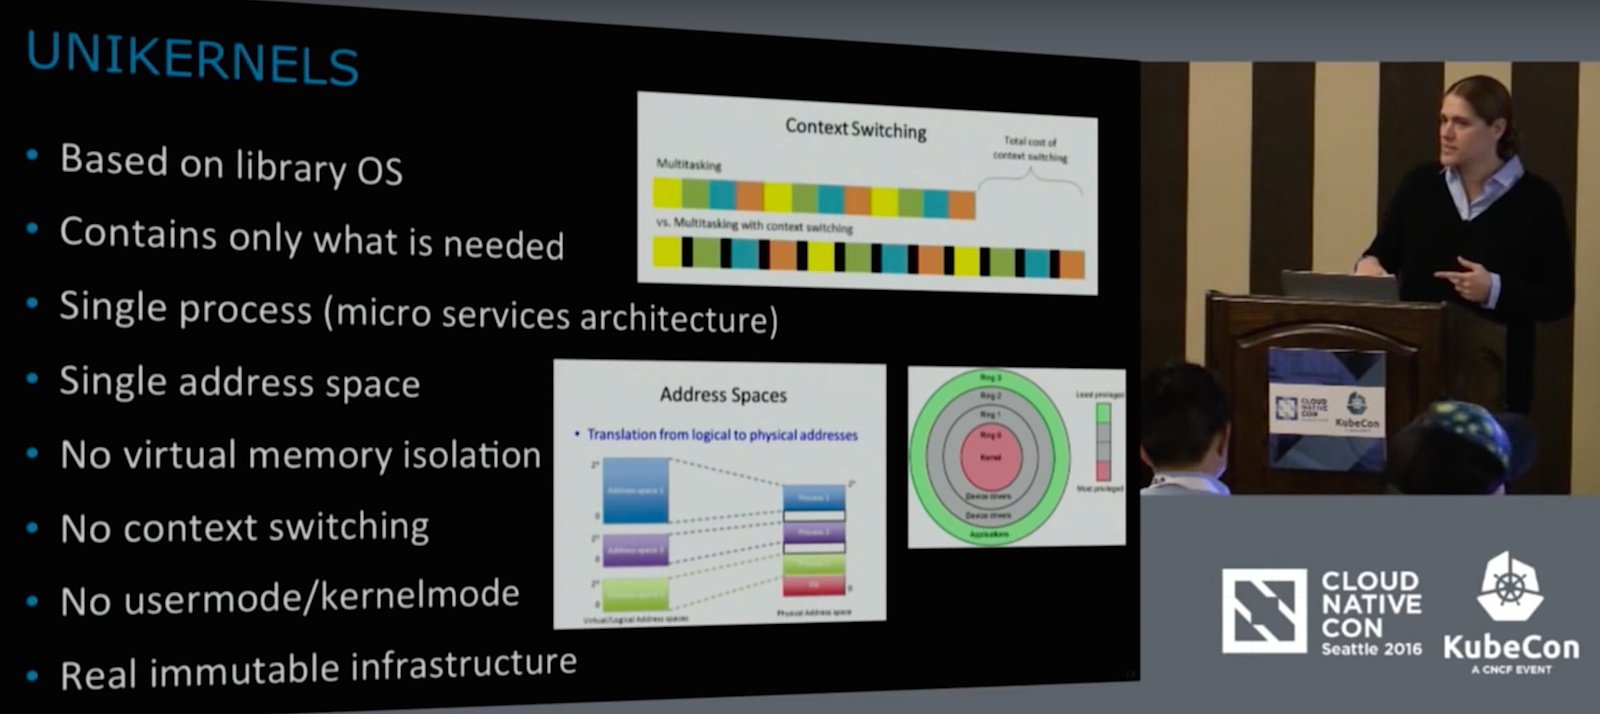
Unikernels aren’t a new concept; the stripped-down, library-specific application machine images have been around for decades. But unikernels are enjoying a renaissance thanks to cloud computing; they offer major efficiencies in resource use and provide a tiny attack service for nefarious online activities. At CloudNativeCon in Seattle in November, Idit Levine presented the open source project UniK (pronounced “unique”) and announced new features to make unikernel creation more attractive and viable, both for cloud computing and Internet of Things devices.
Unikernels haven’t been popular, historically, because they’re not easy to create. Narrowing down the essential libraries and drivers for a unikernel from the full application stack has made unikernels a less attractive option for some developers. That’s the problem UniK is trying to solve, according to Levine, who is the CTO of the Cloud Management Division at Dell EMC, and a member of the technical advisory board for the Cloud Foundry Foundation.
“What we wanted to do is make it easy for you do it, so we will do all the hard work for you, and that’s exactly what UniK is about,” Levine said.
Just as Kubernetes creates application containers for clusters through a simple command interface, UniK is a tool to compile application sources into unikernels. By using unikernels instead of virtual machines, OS kernels can be avoided altogether, saving significant computing resources — and money.
Levine said unikernels mesh very well with microservices architecture; the unikernel runs a single process for a single user, and that’s the same philosophy as microservices, isolating processes and decoupling APIs.
“In order to make something like this we need to make some design choice, and our design choice was, we’re going to run only one single process,” Levine said. “If you’re running one single process and one user, which is what we’re doing in microservices architecture today, then we can be very, very smart about reducing a lot of the complexity.”
UniK offers builds for several different operating systems (MirageOS, IncludeOS, OSv, et al.), types of hardware (Intel chipsets or ARM for IoT devices), and cloud infrastructures (AWS, OpenStack, and Google Cloud), and now fully supports Kubernetes. Levine said the whole goal was to let developers choose what works best for them.
The project team is adding more compatibility all the time; Levine welcomed anyone to join the project and contribute.
For more information, watch the complete presentation below:
Want to learn more about Kubernetes? Get unlimited access to the new Kubernetes Fundamentals training course for one year for $199. Sign up now!
Earlier in this series, I provided a brief overview of NTP and then looked at important NTP options to lock down your servers. In this article, I’ll look at some additional security concerns.
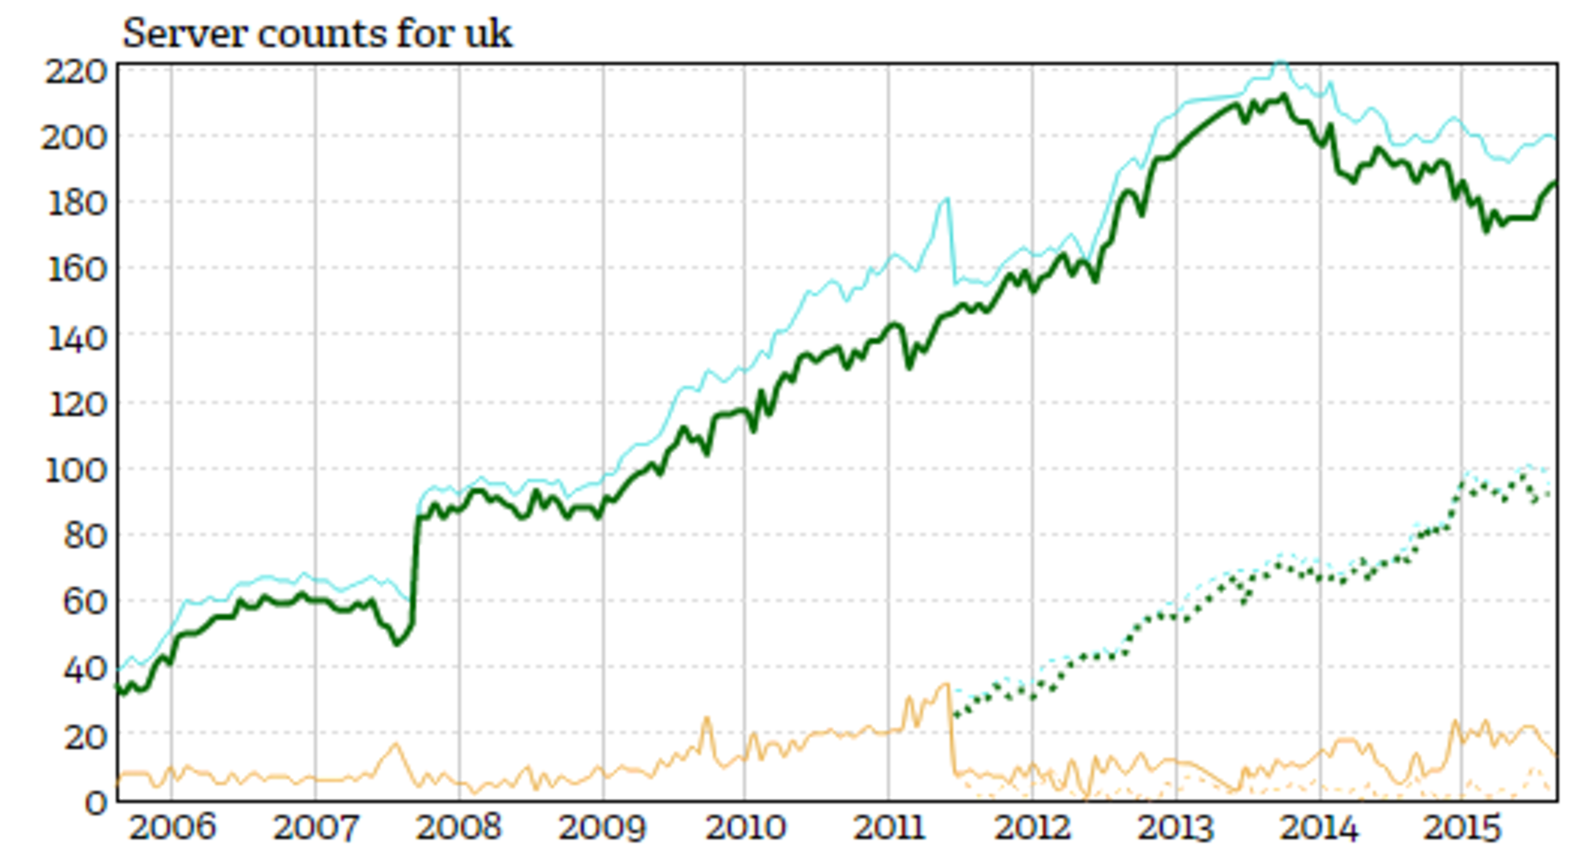
According to the excellent site NTP Pool Project website, which points users at a “big virtual cluster of Time Servers providing reliable easy to use NTP service for millions of clients,” there are 182 active servers for the UK pool in the IPv4 space and 99 available to IPv6 at the time of writing. For reference, they provide useful historical statistics and graphs to presumably keep an eye on any geographical areas which require more resilience, among other things. Figure 1 shows a graph of the available servers for the UK.
Let’s go back to the friendly restrict command, mentioned previously. It can unilaterally “ignore” everything from hosts or subnets, This should deny absolutely everything, indeed packets of all kinds, including ntpq and ntpdc queries.
I also mentioned Kiss of Death packets earlier and adding the kod option to a restrict line means that we will send a kiss-o’-death (KoD) packet if we want help reduce unwelcome packets and introduce rate-limiting of some description.
One other point to note is that using the limited option only denies clock updates if a requests comes up against the rate limits established by the discard command. The limited option doesn’t apply to ntpq and ntpdc queries, which might add more load from a user with nefarious intentions.
A common addition to the restrict line is nomodify. This denies ntpq and ntpdc queries that might attempt to modify the time on an NTP server. As you would expect, however, any queries that return information only are allowed.
You are unlikely to avoid seeing this option: the noquery flag makes certain that you deny all ntpq and ntpdc queries. Be aware, however, that offering up the correct time is still possible despite this being enabled.
If you want to avoid building relationships with other NTP servers (e.g., unless they are successfully authenticated with you), then the nopeer option will allow you to do this. According to the manual, “This includes broadcast, symmetric-active and many-cast server packets when a configured association does not exist.”
The noserve option is simple; it dutifully denies all packets from a machine (or range of machines) except for ntpq and ntpdc queries.
As you might expect the notrust switch enforces who can connect to your NTP server. In fact, it will deny traffic that isn’t cryptographically authenticated. Again quoting from the manual:
“Note carefully how this flag interacts with the auth option of the enable and disable commands. If auth is enabled, which is the default, authentication is required for all packets that might mobilize an association. If auth is disabled, but the notrust flag is not present, an association can be mobilized whether or not authenticated. If auth is disabled, but the notrust flag is present, authentication is required only for the specified address/mask range.”
One final option to pay attention immediately to is called version. This option will be certain to disallow traffic that doesn’t match the current NTP version of your server or client. This can clearly be useful for enforcing that up-to-date versions are used and therefore older security issues present less risk. A similar approach appears in OpenSSH where using the legacy “version 1” is far from recommended; therefore, it is necessary to explicitly enable that version to avoid falling into a potential trap and opening up security holes unnecessarily.
One infrastructure recommendation relates to installing NTP servers and introducing “peering” yourself for improving resilience and capacity. Implementing a peer-to-peer infrastructure within your Stratum 2 servers means that those servers within the peer group allow each other to update their clocks. This, in turn, helps with load balancing and any additional load on their relevant upstream servers. This approach might also be called distributing the time horizontally.
As with all online architectural challenges, there are several other factors to consider. For example, keeping time diligently with three upstream servers and building a complex internal NTP fabric, upon which you come to heavily rely, is of little use if you only have one external Internet connection.
Earlier, I promised to quickly examine how to lock down your firewalling with IPtables, rather than opening up UDP port 123 carte blanche. This might apply to your local NTP client, or if you added such rules to a perimeter firewall all of the clients on your LAN. I’ll look at limiting who you can speak to in order to ensure that only very select, predefined, time servers can connect with you.
I’ll use the “uk.pool.ntp.org” example for familiarity, but in reality you might lock down these rules to three individual servers and not a pool of servers. This is because, although you are assured of the reliability of multitudinous NTP servers being available, you may not want to trust them all. Due to the high churn rate, some could be compromised and cause you unwelcome headaches.
Outbound — egress — traffic rules are slightly more sophisticated than those we use to allow traffic into our machine or network. This is because we want to allow “NEW” time lookups to be performed and also pick up the response when an NTP server responds to such a request with what’s called an “ESTABLISHED” connection. You can achieve that as follows:
# iptables -A OUTPUT -o eth0 -p udp -d uk.pool.ntp.org --sport ntp -m state --state NEW,ESTABLISHED -j ACCEPT
Note that if this were my configuration, I would most likely tie these rules to specific IP addresses.
Conversely, to allow an inbound time check to occur, you can use this fractionally simpler line with just “ESTABLISHED” connections being allowed through:
# iptables -A INPUT -i eth0 -p udp -s uk.pool.ntp.org --sport ntp -m state --state ESTABLISHED -j ACCEPT
Finally, to help clear up any confusion there’s an alternative of sorts to the venerable Network Time Protocol that is worth a quick mention. This option comes in the form of the Simple Network Time Protocol (SNTP). What is interesting is that both timekeeping solutions follow the same packet format and actually, according to RFC 4330, “the NTP and SNTP packet formats are the same, and the arithmetic operations to calculate the client time, clock offset, and roundtrip delay are the same.” So, be confused no longer if you think SNTP is more of a subset of NTP rather than a contender.
SNTP becomes most useful when a fully fledged NTP server infrastructure can’t be justified. An earlier RFC (RFC 2030) talks specifically about not expecting SNTP to be performant at passing on the time to other clients. It also mentions that at the furthest edge of the NTP tree (by that I mean the the leaves, or the highest stratum, as opposed to the branches which then connect to the trunk) is where SNTP implementations are best suited. The RFC also warns that without redundant network links and diverse, resilient configurations, SNTP should not be relied upon for serving the time, just receiving it.
Clearly, however, on lesser powered devices SNTP can be implemented quite happily to use fewer system resources. It should therefore be applicable to a number of scenarios, specifically where the IoT demands time lookups from otherwise low-powered equipment, such as refrigerators or other domestic appliances (which I suspect are likely to remain low-powered from a computing perspective for a relatively short period of time as demands on their functionality grows).
Although I’ve only run through an overview on keeping your clocks correct with NTP, I hope this introduction has explored some of the more important aspects of the subject. I have looked at the configuration, monitoring, and securing of NTP and extolled its value to the integrity of your infrastructure.
You should consider NTP absolutely critical and can now appreciate why it should be one of the first services — possibly directly after DNS — to explore in detail when building infrastructure. Armed with a smattering of IPtables and knowledge of where to find listings of public NTP servers, you are now suitably armed to begin that very task.
Chris Binnie is a Technical Consultant with 20 years of Linux experience and a writer for Linux Magazine and Admin Magazine. His new book Linux Server Security: Hack and Defend teaches you how to launch sophisticated attacks, make your servers invisible and crack complex passwords.
Advance your career in Linux System Administration! Check out the Essentials of System Administration course from The Linux Foundation.
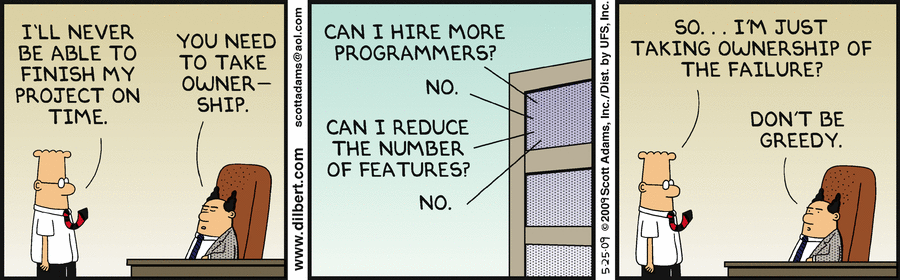
The curse of broken middle management has plagued numerous large organizations throughout the years, and you can find an entire cottage industry around books, training materials and other things designed to “fix” the problem. Either these fixes are inadequate, people don’t listen or just don’t retain knowledge, or, as I believe is usually the case, middle management is really hard to do well. Upper executives have a luxury that middle managers don’t – they can spend all day looking at reports, creating power points, and thinking up crazy stuff for middle managers to do, sometimes by outright edict with little input from anyone else. Red Hat CEO Jim Whitehurst has touched on this subject in his book, “The Open Organization.” “OK!” I can hear you shout in your best internal monologue voice, “But what does this have to do with open source???!!!” I’m glad you asked, but there’s no need to shout!
If you’ve regularly read my articles – and really, why *wouldn’t* you? – you know that I’ve said that open source leveled the playing field of customers, partners and vendors (and individual developers and users). The old hierarchy of vendors and customers led to software that was bulky, overpriced and excessive, and usually left the customer with little choice in the matter. They could either buy bulky, overpriced thing from vendor A, or they could spend a lot of time and effort switching to the other bulky, overpriced thing from vendor B. This was the great innovation and “killer app” of open source. It upended that model entirely and allowed customers greater choice and flexibility. As I think about the frozen middle, I wonder if open source principles could be used to ameliorate that problem as well. This works well in engineering organizations, but similar tactics could work in other types of collaborative settings as well.
When you dive into the frozen middle problem and what can cause organization dysfunction, the topic invariably turns to the subject of “bureaucratic inertia.” At this point people usually shrug their shoulders, roll their eyes, and express exasperation, recommending that no one should beat their head against a wall in search of a solution. What is bureaucratic inertia, and what causes it? There are a couple of primary causes, some of which I’ve personally witnessed, and others I’ve read about in business case studies:
Here’s where it gets interesting. What if internal projects were run just like any other open source project? The tooling for software engineering projects is probably more mature for this purpose, but the same principles could apply anywhere. It would serve the same objectives as open source did for the customer-vendor relationship. Now, instead of a strict heirarchy with little information ending up where it should, everyone in the organization collaborates, with information flowing where it should, whenever it’s requested. Think of it as equal parts Innersource, DevOps, and open source community management. Lest anyone fear that I’m suggesting an “Ark B” strategy for middle management, I believe that everyone in the organization has a role to play, including middle management. It’s not that there shouldn’t be hierarchy, it’s that hierarchy should be designed to function optimally.
In an open source collaboration scenario, edicts are not issued without close collaboration with those implementing the strategy. Strategies and implementation plans are developed transparently, with input from interested parties at every stage. This way, everyone owns it. In larger organizations, such initiatives can suffer from a glut of input, but open source projects have found ways to solve that problem. There is where a hierarchy comes in. In open source projects, these hierarchies are voted in by project members, with managers attaining their positions according to their contributions. This may not work in practice in many organizations, but managers can serve the same purpose. In an open source project, the manager’s job is to facilitate communication, unlock bureaucratic roadblocks faced by individual contributors, review their work, and use their influence to prevent stupid decisions both in upper management and from individuals. Upper management can benefit because they’re no longer divorced from the day-to-day experience, seeing more clearly the challenges faced by everyone else. Individual contributors benefit because they have more access to project leaders and, yes, can bypass middle management when appropriate. Yes, there’s a hierarchy, but it’s not rigid, and that’s important.
I’m going to stop here for this first post on the subject. There are several different directions I could go in a subsequent post or series, but I’d like to hear from the readers first. What are your experiences with middle management? Upper executives? Individual contributors? How did you push through bureaucratic obstacles? Did you have to “hack the hierarchy”? Let’s use this as the starting point of a conversation.