Home Blog Page 657

Math in V8 Is Broken; How Do We Fix It?

JavaScript has become increasingly more popular, especially with the introduction of Node.js, which has allowed full-stack JavaScript development. As this 20-year development language continues to rise, a group of individuals began to notice something: Math in V8 (a JavaScript engine) is broken.

In advance of Node.js Interactive, to be held Nov. 29 through Dec. 2 in Austin, we talked with Athan Reines, software engineer at Fourier, about the importance that JavaScript Math library has to the overall community; how they discovered underlying implementations were not accurate; and why a group of individuals are working to fix this.

Linux.com: What is the general importance of the built-in JavaScript Math library?

Athan Reines: The built-in JavaScript Math library is often a developer’s first introduction to math in JavaScript. Developers use it for generating unique ids, computing exponential back-off times, manipulating colors, animating, detecting collisions, rendering 3D graphics, simulating physics, calculating performance metrics, and much more. Almost all applications, server and browser alike, depend on the built-in Math library.

Linux.com: How did you figure out the underlying implementations were not accurate, performant, and/or correct? How does this affect users when they work with this library?

Athan Reines: We (co-authors and I) are currently developing libraries for numeric computing in JavaScript. As part of this work, we wrote libraries for higher order special functions, like gamma, beta, erf, and others. When testing our implementations against other environments (R, Python, Julia), we noticed that our results often deviated significantly from reference implementations. To our surprise, we discovered that much of the deviation was due to precision issues in the built-in JavaScript Math library. Compounding problems, we noticed that precision varied across JavaScript engines.

For many common application tasks, minor deviations in precision are unlikely to have a significant effect. However, for numeric computing and applications requiring high precision, poor precision does have a significant effect due to accumulated error. Especially since the built-in Math functions are frequently used by higher-order functions, small deviations compounded many times can lead to significant drift from the “true” value.

Additionally, the ECMAScript specification for many Math functions does not require either a specific algorithm or a minimum precision. Algorithms are at the discretion of those implementing the specification, which means that browser vendors frequently implement different algorithms. Some vendors choose speed over precision, while others choose precision over speed. Because of cross-browser variability, applications cannot guarantee consistent numerical results, thus affecting portability.

Linux.com: What are some efforts taking place to fix this issue and/or what improvements are being made?

Athan Reines: Over the past several years, various individuals on the ECMAScript technical committee (TC39) have raised the issue that the built-in Math library is underspecified. However, an updated specification does not seem likely anytime soon. While vendors seem open to a minimum precision requirement, they want to retain the ability to choose the underlying implementation.

Over the past two years, both the Firefox and Chrome teams have made efforts to standardize their Math implementations. Both teams chose FDLIBM for reference implementations. While these efforts are a step in the right direction, unless all vendors implement the same algorithm, individuals developing portable numeric compute applications must develop for the lowest common denominator; i.e., the vendor with the least precise and/or slowest algorithm.

Currently, community-driven solutions are spearheading most innovation with regard to Math in JavaScript. I am part of one such effort, stdlib. Our work provides robust, rigorous, and performant implementations for standard math functions. Each implementation is tested against multiple environments and measured against built-in equivalents. For many implementations, we have found that we can match and sometimes exceed the performance of built-in methods. Because our implementations are vendor independent, we avoid portability issues, ensuring consistent results across environments.

Linux.com: Given that JavaScript is more than 20 years old, why now? What has changed to fuel user demands for better Math libraries?

Athan Reines: The big change is Node.js. Node.js gave JavaScript a legitimacy beyond being a toy language people used in the browser to build web applications. As companies continue to realize the benefit of full-stack JavaScript development, demand continues to grow for JavaScript numeric computing libraries in order to obviate the need for polyglot architectures.

Furthermore, browser applications have moved beyond mostly static applications and games. Applications now are increasingly sophisticated and increasingly leverage a user’s own compute capacity. Part of the allure of numeric computing in JavaScript is to outsource what have traditionally been viewed as server-side computation tasks to client-side applications to decrease server load and increase application responsiveness.

Linux.com: Is there anyway for people to get more involved in these efforts or to stay in the loop on what’s being done here?

Athan Reines: The easiest way to stay in the loop is to follow development of stdlib, as we continue to develop facilities for numeric computation. To contribute, feel free to reach out to either me or Philipp Burckhardt, and we will be happy to get you started. To keep up-to-date with TC39, follow TC39 meeting agendas and Rick Waldron’s corresponding notes.

Lastly, follow Chrome and Firefox issue threads for additional built-in JavaScript Math library development.

View the full schedule to learn more about this marquee event for Node.js developers, companies that rely on Node.js, and vendors. Or register now for Node.js Interactive.
Monitoring Network Load With nload: Part 2

In the previous article, I provided an introduction to nload, covering some background, installation, and basic usage. Here, I’ll build on that information and show some specific examples of using nload with various options.

Runtime Options

You can launch nload with a number of options, so let’s explore some of those now.

Previously, I discussed the effect of making changes to the “refresh interval” and “traffic averages” settings. The setting which you probably shouldn’t drop much lower than the default — for fear of losing accuracy — is the -t option, which affects the “refresh interval.” If you decide to do so, then you can move away from the default 50 milliseconds to using a quarter of a second (250 milliseconds) by launching nload with this option:

# nload -t 250 

When it comes to “traffic averages,” we can adjust the period used in the calculations by using the -a option as follows. Note that this value is in fact in seconds and not milliseconds, and it defaults at five minutes (300s).

# nload -a 60

Consider another option now. Picture the scene: your Internet connection is via a gigabit network link but your ISP only allows you to use 100Mbit of that connection. Any network tool querying your network link will see a gigabit link speed as being available. Clearly, however, this is not of any use to you. The clever nload tool lets you configure the throughput ceiling, which you will monitor. As you continue to use the tool, do bear in mind that you’ve altered this setting just in case you see unusual spikes above that ceiling. Otherwise, it’s as simple as altering the setting like this:

# nload -i 100000

The “100000” value above is in kilobits-per-second (as scaling settings in nload generally are) and represents 100Mbit if my calculator is working properly. Note that the -i option is only for inbound (ingress) traffic, and the -o option is for outbound (egress) traffic.

On that note, should you wish to alter the default unit of measurement for traffic (as I almost always do when moving between different network capacities), then you can launch nload in a variety of differing ways. Here is an example of making nload use kilobits-per-second (kbps) units by using the -u option:

# nload -u k

In the case of nload and the above example, there’s actually no need to run that command, because that’s the default setting (“kbps” is a very good choice on all but very fast networks in my opinion).

Looking at Table 1, we can see the other available options for unit measurements.

Bits

Bytes

Throughput units of measurement

h

H

Human readable formatted (otherwise known as auto mode)

b

B

Bits per second or Bytes per second

k

K

Kilobits per second or Kilobytes per second (the default is “k” or “kbps”)

m

M

Megabits per second or Megabytes per second

g

G

Gigabits per second or Gigabytes per second

Table 1: Unit measurement traffic throughput options.

Let’s continue looking at another group of runtime options available to nload. Along the same vein as our unit measurements, in terms of network throughput, we can also change how the amount of data transferred is presented to you.

In Table 2, we can see the possible upper and lowercase options. Note that this time we use the uppercase -U option to effect transfer data measurements and that the Bytes and Bits columns are in a different order due to the default setting being for megabytes (or “M”). This is almost the same as Table 1, but there’s no per-second measurement as it relates to file sizes essentially.

Bytes

Bits

Data transfer units of measurement

H

h

Human readable format (auto mode)

B

b

Bytes of data or bits of data

K

k

Kilobytes of data transferred or kilobits

M

m

Megabytes of data or megabits of data

G

g

Gigabytes of data transferred or gigabits

Table 2: The available nload data transfer unit measurement options.

For clarity, here’s a quick example of altering the data transfer measurement:

# nload -U K

This option changes moves off the default megabytes to displaying data collection values in kilobytes.

Live Options

There are also a few commands which you can use while nload is running.

I mentioned having more than one device displayed on the console at once but you additionally have the ability to quickly move between devices. You can do this by simply pressing the Left and Right arrow keys (the cursor keys) on your keyboard. You won’t get lost because the number of windows available to you are paginated. How many pages can be accessed and which page you are currently on is dutifully displayed at the top of the window. Alternatively, you can achieve the same functionality by hitting the Enter key or the Tab key to cycle through the network interfaces visible to your machine.

As shown previously, the available options are displayed in a box at the top of the console. To toggle this Options Window on and off, you can simply hit the F2 key. To move around the Options Window, thankfully, there’s not much to learn; it’s very intuitive. Simply use the cursor keys on your keyboard to move around the box. Once you’re over the setting you want to adjust, simply use the plus and minus keys on your keyboard to increment and decrement the setting. Once you’re happy with your selections, just hit the F2 key again to hide the Options Window.

If you make a mistake and your display isn’t as you would like, then you can load up any saved settings (we’ll look at this in a moment) by using the F6 key. If you’ve hit the sweet spot with your config settings and want to overwrite your saved config file, then it’s as simple as hitting the F5 key.

I have to admit that I got the F5 and F6 keys the wrong way around at first (probably because I associate the F5 key with reloading a browser’s page). Just create a backup of your saved config to an unrelated filename if you’re worried that you’ll do this and lose configs.

If you wanted to quit nload, then you can either reach for the ever-present Ctrl+C key combination or additionally simply hit the lowercase “q” key.

Saved Config

There are two main files that nload uses for saving its config. The system-wide configuration file is called /etc/nload.conf. We can affect all users by editing options within this file, as opposed to an individual user’s settings. To change options for an individual, it’s as simple as creating and editing a file in your home directory such as:

# pico -w /home/chrisbinnie/.nload

Follow the options that we’ve discussed and any in the system-wide config file to populate this file.

Troubleshooting

Fear not if you get stuck. In addition to running this command below, there are of course other routes to receiving assistance:

# nload --help

There’s a useful mailing list available where you could ask questions, and archives of previous mailing list discussions are also available. The useful netiquette applies. Be courteous and respectful, and don’t expect every list member to immediately jump to your rescue if you haven’t made any efforts yourself.

Summary

Watching the mighty nload in action can be a bit mesmerizing at times. And, running it alongside other console windows nload is a real lifesaver. During periods of heightened stress, it launches almost instantly, and you can usually easily discern the required information.

I hope it goes without saying that I recommend trying nload a few times before an outage or other stressful interlude. Having your boss lean over your shoulder and witness your lack of understanding of your tool during a problem is not ideal, I’m sure you’ll agree.

When you are awakened at 4am and can glean the pertinent information from nload with no effort at all — you will be glad you tried it out beforehand.

Chris Binnie is a Technical Consultant with 20 years of Linux experience and a writer for Linux Magazine and Admin Magazine. His new book Linux Server Security: Hack and Defend teaches you how to launch sophisticated attacks, make your servers invisible and crack complex passwords.

Advance your career in system administration! Check out the Essentials of System Administration course from The Linux Foundation.

Fujitsu’s Open Source Journey — From Consumer to Contributor

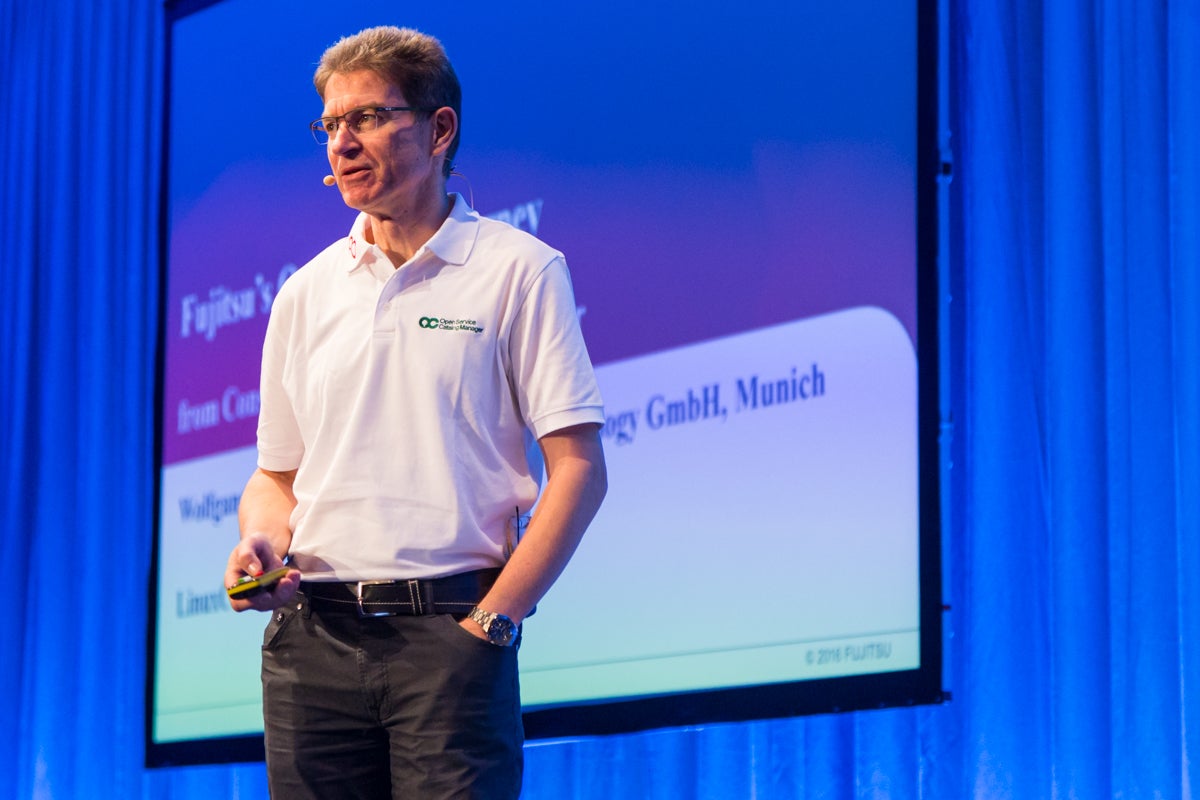
Open source is a journey for many companies as they move through a process that seems a bit like magic when releasing an open source project. Recently at LinuxCon Europe, Wolfgang Ries, CMO at Fujitsu Enabling Software Technology GmbH, talked about the company’s open source journey and how they still think of themselves as apprentice contributors in the process of learning how to improve their open source contributions.

Ries began by talking about how open source is a bit like magic, referring back to Arthur C. Clarke’s quote, “Every sufficiently advanced technology is indistinguishable from magic.” He says, “If you look at all the social problems that open source can solve, it becomes even more obvious that open source is really magic.”

One example, is the National Ebola Response System in Sierra Leone, which was built using open source software, and in Sierra Leone, open source software is credited with restoring the “faith in the ability of government to be able to run its systems honestly.” He mentioned another example from DefCon at the DARPA Cyber Grand Challenge, which was designed to show computers fixing other computers. An open source project won the DARPA prize, and he suggested that “you could think of it as open source actually being able to fight Skynet in the future.” If all of this is a bit like magic, he suggests that “you have to be careful with how you deal with it” to avoid things going horribly wrong, like when the apprentice tries to do magic without the master being around in the The Sorcerer’s Apprentice by Johann Wolfgang von Goethe. 

Open Source Catalog Manager

About a year ago, Fujitsu created the Open Service Catalog Manager (OSCM), their first full software project contribution to the open source space. Ries describes this a “winding road” where they moved through several different steps to ultimately release the OSCM as an open source project. They started with “Consensus Ridge” to decide whether Fujitsu should even do this as an open source project, which was easily answered because so many of their customers and the industry are demanding open source solutions.

The next hurdle was the “Confidence River” where it took a bit of time to evaluate patent risk, security, and other architectural considerations to decide whether they had what it takes to create this open source project. The next phase on their journey was through the “Mechanics Maze” to figure out exactly what online materials, documentation and other resources were needed to make OSCM a success. “Governance Desert” was the next section of the winding path to select a license, contributor processes, and other governance considerations. The final stop on their journey is at “Community House” where Ries admits that they are at LinuxCon to “entice people to join” and build a community around OSCM.

To get more details and learn about contributing to OSCM, watch the entire keynote below.

LinuxCon Europe videos

Keynote: Fujitsu’s Open Source Journey – From Consumer to Apprentice Contributor

About a year ago, Fujitsu created the Open Service Catalog Manager (OSCM), their first full software project contribution to the open source space. Wolfgang Ries describes the journey to this milestone.


How Unikernels Can Better Defend against DDoS Attacks

On the episode of The New Stack Makers podcast, Dell EMC CTO Idit Levine, an EMC chief technology officer at the cloud management division and office of the CTO, discussed how unikernels are poised to offer all of the developer flexibility afforded to containers, while striving for better security and integrations with many of todays top container platforms. 

At KubeCon earlier this month, Levine and the rest of the team behind the open source unikernel compilation and management platform, Unik announced new features for Unik designed to bolster both unikernel adoption and community involvement with the project moving forward. These changes included Kubernetes integration, with users having the ability to run Unik side-by-side with Kubernetes, and adding support for the Google Cloud Platform after continued requests to do so from the community.

Read more at The New Stack

Git Behind the Curtain: What Happens When You Commit, Branch, and Merge

I think that the first thing to understand about Git is that it’s not strictly a source control system; it’s more like a versioned filesystem that happens to be good at source control. Traditionally, source control systems focused on the evolution of files. For example, RCS (and its successor CVS) maintain a separate file in the repository for each source file. These repository files hold the entire history of the file as a sequence of diffs that allow the tool to reconstruct any version. Subversion applies the idea of diffs to the entire repository, allowing it to track files as they move between directories.

Git takes a different approach. Rather than constructing the state of the repository via diffs, it maintains snapshots of the repository and constructs diffs from those (if you don’t believe this, read on).

Read more at DZone

Resolving Conflict

In a perfect world, we would all get along with our coworkers and bosses all the time. Unfortunately, we don’t live in a perfect world.

While most of us make our best efforts to avoid conflict at work, occasionally it is unavoidable. Here are some of my best tips on how to make all of your conflicts in the workplace healthy and (hopefully) productive, so you can move on and get back to what really matters.

1. Give up on the idea of “winning”

The best way to win an argument is to let go of the idea that you actually have something to “win.”

Winning, in this case, doesn’t mean getting your way or showing the opposition how they are wrong. Instead, it means being the person who helps everyone get on the same page so everyone can move forward.

Read more at ACM Queue

A Tale of Cylinders and Shadows

Taking a closer look as to why GTK+ experienced significant speed issues when used with Wayland and HiDPI screens.

—

Written by Gustavo Noronha, Web Domain Lead at Collabora.

Like I wrote before, we at Collabora have been working on improving WebKitGTK+ performance for customer projects, such as Apertis. We took the opportunity brought by recent improvements to WebKitGTK+ and GTK+ itself to make the final leg of drawing contents to screen as efficient as possible. And then we went on investigating why so much CPU was still being used in some of our test cases.

The first weird thing we noticed is performance was actually degraded on Wayland compared to running under X11. After some investigation we found a lot of time was being spent inside GTK+, painting the window’s background.

Here’s the thing: the problem only showed under Wayland because in that case GTK+ is responsible for painting the window decorations, whereas in the X11 case the window manager does it. That means all of that expensive blurring and rendering of shadows fell on GTK+’s lap.

During the web engines hackfest, a couple of months ago, I delved deeper into the problem and noticed, with Carlos Garcia’s help, that it was even worse when HiDPI displays were thrown into the mix. The scaling made things unbearably slower.

You might also be wondering why would painting of window decorations be such a problem, anyway? They should only be repainted when a window changes size or state anyway, which should be pretty rare, right? Right, that is one of the reasons why we had to make it fast, though: the resizing experience was pretty terrible. But we’ll get back to that later.

So I dug into that, made a few tries at understanding the issue and came up with a patch showing how applying the blur was being way too expensive. After a bit of discussion with our own Pekka Paalanen and Benjamin Otte we found the root cause: a fast path was not being hit by pixman due to the difference in scale factors on the shadow mask and the target surface. We made the shadow mask scale the same as the surface’s and voilà, sane performance.

I keep talking about this being a performance problem, but how bad was it? In the following video you can see how huge the impact in performance of this problem was on my very recent laptop with a HiDPI display. The video starts with an Epiphany window running with a patched GTK+ showing a nice demo the WebKit folks cooked for CSS animations and 3D transforms.

After a few seconds I quickly alt-tab to the version running with unpatched GTK+ – I made the window the exact size and position of the other one, so that it is under the same conditions and the difference can be seen more easily. It is massive. Video: https://www.youtube.com/watch?v=XQVqSms5guU

Yes, all of that slow down was caused by repainting window shadows! OK, so that solved the problem for HiDPI displays, made resizing saner, great! But why is GTK+ repainting the window even if only the contents are changing, anyway? Well, that turned out to be an off-by-one bug in the code that checks whether the invalidated area includes part of the window decorations.

If the area being changed spanned the whole window width, say, it would always cause the shadows to be repainted. By fixing that, we now avoid all of the shadow drawing code when we are running full-window animations such as the CSS poster circle or gtk3-demo’s pixbufs demo.

As you can see in this video, the gtk3-demo running with the patched GTK+ (the one on the right) is using a lot less CPU and has smoother animation than the one running with the unpatched GTK+ (left).

Pretty much all of the overhead caused by window decorations is gone in the patched version. It is still using quite a bit of CPU to animate those pixbufs, though, so some work still remains. Also, the overhead added to integrate cairo and GL rendering in GTK+ is pretty significant in the WebKitGTK+ CSS animation case. Hopefully that’ll get much better from GTK+ 4 onwards.

System76 Oryx Pro Review: Linux in a Laptop Has Never Been Better

Laptops preloaded with Linux aren’t as rare as they used to be. In fact, big name hardware companies like Dell have whole lines of laptops that ship with Ubuntu installed, and if you want to stretch things a bit you could argue that a Chromebook is a kind of Linux machine (though it takes a bit of tinkering to get actual Linux installed). Still, there’s no question the Linux user of today has a wealth of options compared with the dark ages of just a few years ago when “I use Linux” was code for “I spend all my time looking for hardware drivers.”

Today, what remains unusual even in the midst of this growing interest in PCs shipping with Linux is a company that sells nothing else. There are a handful of organization that do just this, however, and they have done so for some time. These entities range from longtime Linux supporters like System76 to newer efforts from the likes of Purism, which began life with an impressive crowdfunding campaign that raised more than a $1 million to create a line of sleek, Apple-inspired but completely free-software laptops.

Read more at Ars Technica

How to Upgrade Fedora 24 to Fedora 25 Workstation and Server

This guide will walk you through the various steps you can follow to upgrade your system to Fedora 25 from Fedora 24 using both graphical user interface (GUI) and command line methods.

Although the primary method of upgrading has been provided via the command-line, however, if you are using Fedora 24 workstation, you can take advantage of the GUI mechanism.
Read complete article at Tecmint